OneLake without another copy problem
Shortcuts, mirroring, lakehouses and warehouses can reduce movement, but teams still need rules for authoritative data, domain ownership and when duplication is justified.
Robra supports Microsoft Fabric from readiness and capacity planning through data migration, engineering, warehousing, real-time analytics, semantic modeling and Power BI delivery. Teams can add focused help for one workload or establish the governance, release process and support coverage needed to run Fabric as a shared enterprise platform.
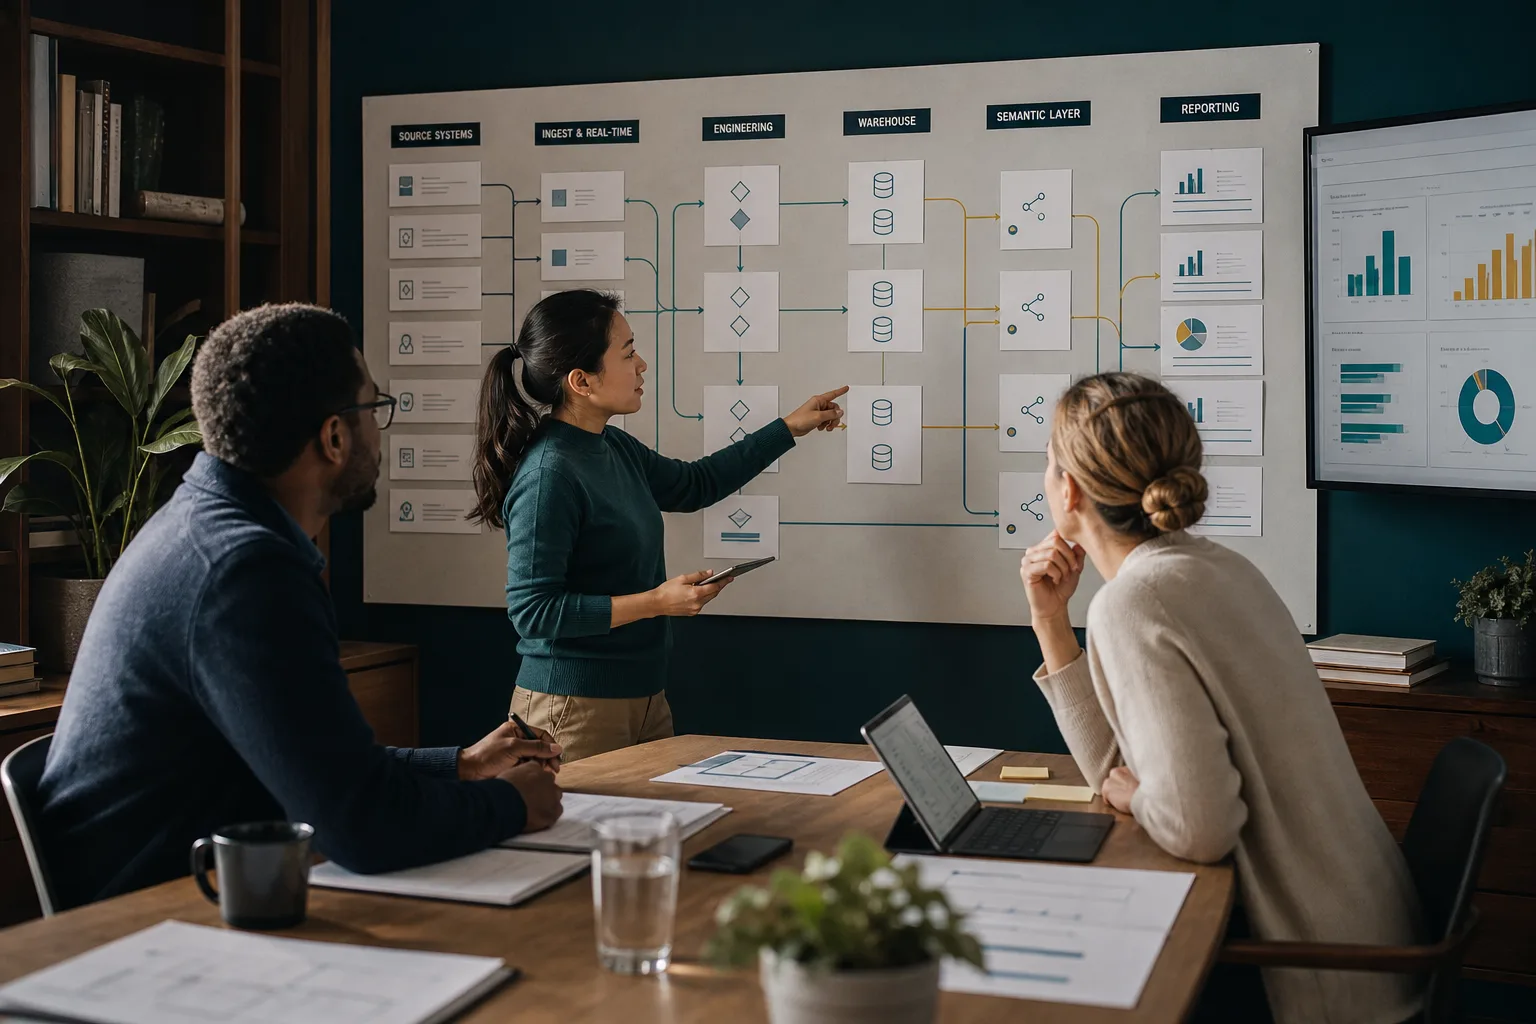
OneLake, Data Factory, lakehouses, warehouses, Real-Time Intelligence and Power BI share one platform and capacity model. That convenience also links workspace design, security, deployment and performance. A pipeline change can affect a semantic model, while an inefficient query or refresh can consume capacity needed by unrelated teams.
Robra helps design the domain, workspace and capacity model before moving workloads. Data engineers, warehouse and Power BI specialists then build, reconcile and release the platform with governance, monitoring and support ownership that fit the organization.
Talk to an expertReview data sources, existing Azure and Power BI assets, capacity, security, governance and team readiness.
Build Fabric workspaces, pipelines, lakehouses, warehouses, databases, semantic models and reports.
Connect batch, streaming and mirrored data through Data Factory, shortcuts, gateways and event services.
Validate transformations, reconciliation, semantic logic, access, performance and report behavior.
Promote workspace items through Git and deployment pipelines with controlled data and configuration changes.
Resolve capacity pressure, failed pipelines, refresh issues, model defects and access problems after launch.
Improve Direct Lake design, models, pipelines, workload placement, cost and self-service usability.
Provide named engineering, Power BI, governance and capacity administration support.
The strongest implementations decide where data lives, who owns each item and how shared capacity is protected before self-service expands.
Shortcuts, mirroring, lakehouses and warehouses can reduce movement, but teams still need rules for authoritative data, domain ownership and when duplication is justified.
Pipelines, Spark jobs, warehouse queries, semantic-model refresh and interactive reports compete for capacity. Monitoring needs to connect throttling and consumption to the workload that caused it.
Direct Lake removes some refresh constraints, not the need for clean dimensions, measures, security and model ownership. Performance depends on the table and model design beneath the report.
Domains, workspaces, Git integration and deployment pipelines must account for item dependencies and environment-specific configuration. Promotion should not depend on someone remembering a manual setting.
Built around your team
Start with one named specialist, a coordinated project team, flexible ongoing support or a shared managed service. Robra adapts the team as priorities change and keeps context with the people doing the work.
One or more named specialists join your team. You set the day-to-day priorities, and Robra keeps the support aligned as the work changes.
A coordinated team covers selected workstreams or the full program alongside your sponsors and internal leads.
Keep a consistent core team available for releases, enhancements, support issues and short bursts of functional or technical help.
Robra coordinates the service with your team. Priorities, coverage and ways of working are built around your environment and adjusted as needs change.
Yes. We assess the existing Power BI, Azure, warehouse and lake estate by workload, dependency, performance, governance and cost. The result can be a phased move, coexistence pattern or a recommendation to leave a workload in place.
Yes. Robra can coordinate Data Factory, lakehouse, warehouse, real-time, semantic-model and reporting work so source logic and business measures are designed and tested together.
Yes. We trace utilization to pipelines, Spark, SQL, refresh and interactive activity, then address scheduling, model design, query behavior, workload placement and capacity administration.
Yes. The migration team can scale down to a consistent core covering platform administration, failed workloads, model changes, release coordination and improvement work.
We will map the dependencies and make the first move practical, with engineering and support that can flex as the platform grows.